Logic is the study of what it is for one thing to follow from another. In the 1930s logicians asked what a mechanical procedure could and couldn’t decide, and by 1936 they had arrived at the idea of a machine that can carry out any computation. That machine is the computer.1
Plenty of courses stay with the older part of this story, and it’s a fine story. This one starts from the computer instead, because over the last century logic has found its biggest home in computer science. The quickest way to see why, I think, is to start where you’ve already met it: a red line.
At some point your compiler has refused to run your code. Before the program ever started, a red line appeared under something, and the compiler wouldn’t go any further. The function hadn’t been called and no input had been tried, and still the compiler was sure enough to refuse. Sure of what? And what entitles it to be sure? Certainty that has cost nothing is either a swindle or a theorem, and this chapter is an attempt to find out which.
Inside the machine everything is bits: s and s, “on” and “off”. We use patterns of them, thirty-two at a time, to stand for information: an integer, a few letters of a string, a boolean. The meaning comes from us; the processor doesn’t know and doesn’t care. Asked to combine a string and a number, it will do so without hesitation. The little red line is a sanity check that stops it when the result would be unintended or, worse, dangerous.
In 1999, after years of effort, NASA’s Mars Climate Orbiter, built to be the first interplanetary weather satellite, reached Mars and promptly vanished. It passed behind the planet and radio contact was never restored, so we don’t know exactly what became of it. This was not meant to happen. The orbiter hadn’t followed the path intended, and yet every calculation was correct. What had gone wrong? Not the physics, and not the arithmetic, but something subtler: one program reported a figure in pound-force seconds, and another read it as newton-seconds (Mars Climate Orbiter Mishap Investigation Board, 1999). No test caught the fault. A checker that knew the kind of each number would have refused the hand-over, and that is what the little red line in your code is.2
Today almost every language you use has such a checker.3
Put like that, the job sounds modest: a spell-checker for numbers. But there is a more worrying sort of failure. A few lines of code can, quite by accident, run for ever, using up resources as they go. Such a program never outputs anything, so it is never caught in an error; it just goes on, like a loop with no exit. I call such programs monsters, because they are as dangerous as they are hard to spot. The little red line was invented to keep them out too. How can a checker that looks only at the kinds of things do that? That is the question this chapter is built around.
Part 1 is about type-checking: the red line the compiler draws. There are hundreds of languages, each with a checker of its own, and no two of them look alike on the page. They all work on the same principles, though, and those are what we want to study. So we’ll set aside any particular language and work at the level of computation itself.
For that we take up a proposal Haskell Curry made in the 1920s, before there were any computers. Curry wanted to understand the most mechanical step in all of logic, putting one thing in place of a variable in another. In effect, he wanted to understand what it is to compute with functions. His proposal comes in three parts.
Everything is a function, and the only thing to do with a function is to apply it to something.
To compute is to rewrite: a function applied to its arguments is replaced, by a fixed rule, with what it gives back.
Two functions are enough to start from: one that throws an argument away, and one that shares an argument out.
What comes out is a language with no features at all, and it computes everything that any language you care to mention can. Curry’s own reasons were logical rather than practical, and the chapter ends with them (§1.7).
1.1 Combinator Algebra
Our job in this section is to make Curry’s outline exact: to say precisely what the terms are, and precisely how they are rewritten.
Definition 1.1 (terms, and combinators). Fix two constants, and , and a stock of variables . The terms are defined inductively:
Each constant, and , is a term.
Each variable is a term.
If and are terms, then is a term: the application of to .
Nothing else is a term.
A term without any variables is a combinator.
In one line, with and standing for terms already built,
Writing out every bracket soon gets tiresome, and it makes a term hard for the human eye to read. Here, for instance, is a term with every bracket written:
One gets lost matching each opening bracket to its partner. So we adopt the usual convention, which lets us drop most of them: application groups to the left. Thus means , and we need to write brackets only when the grouping is not to the left: and are different terms, the first being applied to , the second applied to . Under this convention the term above comes out as
We use the convention throughout, and it soon becomes second nature.
On their own, terms just sit there. We want them to do something, and we allow them exactly one kind of action: rewriting. We write , with a squiggly arrow, to say that steps to , that is, that one rewrite turns into . There are infinitely many terms, and we can’t say what each of them does. Nor do we need to. It is enough to say what and do, and how a step taken in one part of a term becomes a step of the whole.
Definition 1.2 (reduction). The relation , read “ steps to ”, is the one given by these rules:
A rule says: whenever what is above the bar holds, so does what is below. The rules () and () have nothing above the bar, so they hold outright, whenever a term has their shape; they are the two ways to rewrite. In words, keeps the first of two arguments and drops the second, and hands its third argument to both of the others and applies the first result to the second.
The rule () says that if , then : a step in the function is a step of the application. The rule () says the same of the argument. Since every term is built by application, between them they reach every part of a term. To show that is to find rules that stack up to it, each bar’s conclusion standing above the next bar.
The rules are written with every bracket, because the brackets say which term is meant. With the convention, () reads and () reads ; the pair round stays because that grouping is not to the left. Here are four steps, each written first with its brackets, as the rules see it, and then as we write it.
| With the brackets | As written | Rules |
|---|---|---|
| () | ||
| (), then () | ||
| () | ||
| (), then () |
The first row is the rule () itself, with for and for . In the second, the brackets show that has two arguments, not three, and that is the function in a larger application whose argument is ; so () carries the step. In the fourth, the part rewritten is the argument, and () carries it. Keep the hidden brackets in mind in everything that follows: most of the mistakes you can make in this chapter are mistakes about where they go.
Example 1.3 (a run, rule by rule). Run the term , taking the step inside it first. (It could also step by () straight away; §1.2 is about such choices.) The first step rewrites , deep inside the term, and four rules stack up to it:
Read it from the top. () rewrites to . Then () carries the step into the argument of , and (), twice, carries it out past and then past , one application at a time. Each bar below the first puts back one pair of the hidden brackets.
The second step needs one rule, since the whole term now has the shape of the left-hand side of (), with for , for and for :
The third rewrites the argument , so () carries it:
Now has nothing left to rewrite, and the run is over.
Nobody draws stacks like these: a step is a step, and the rules only say which ones there are. We write a run as a chain instead, one step per line, with the rules it used on the right:
Often even that is more than we need, and we name only the step at the top of the stack: “the step”, “the step”. The rules for getting inside a term are always () and (), as many times as it takes.
Such a chain is a run: a sequence of steps
We write , read “ runs to ”, when some run from ends at . The run may be of any length, zero included, so always. The run above shows that .
Here’s a way to picture a term: it is a machine with a single slot. You put one thing in, and something may come out. Often what comes out is another machine, with a slot of its own, waiting for the next thing. The constant , for instance, is a machine that wants two things, but it can take them only one at a time. Put in, and out comes a new machine, , which ignores whatever it’s given next and hands back . Put into that, and out comes . So is two machines used one after the other, , and that is the bracketing the convention supplies.
In the same way is a machine that wants three things: is a machine waiting for two more, a machine waiting for one, and is the moment it has all three and does its work. Nothing is ever fed two things at once. Taking arguments one at a time is called currying,4 and it’s why application groups to the left: a call with several arguments is a chain of single applications, is the commonest shape there is, and grouping to the left lets it go without brackets.
A machine still short of an input does nothing: it waits, and there is no step to take in it. The term is one, and so are and on its own. None of them is wrong; each is a function waiting for another argument. Why not simply say in the grammar that takes two arguments and three? One could, but it would bring a tiresome bureaucracy for no gain, and it would hide something the machines make plain: , a function with one argument still to come, is a perfectly good term in its own right.
The function that returns its argument unchanged isn’t one of the two constants, but the language has it all the same. Write for , a name for a term and not a new constant. Whatever is, , by an step and then a step.
Example 1.4 (the identity). Here is the run of on an argument:
Example 1.5 (a puzzle about brackets). The bracket convention has to be taken seriously: applied carelessly, it seems to give one term two different results. Run , and to keep the runs short count the two steps of as one. Two runs seem to be on offer:
One of these is not a run at all, and it is the second. To see why, put the brackets in. The term is : is applied to , the result to , and that result to .
Nowhere in the term is applied to . They stand next to each other on the page, but is one argument of and is another, so the step of the second run has nothing to rewrite. Only one step is available, and . The second run was really about a different term, , in which the brackets put and together; Exercise 1.8 runs it.
Terms built from constants by application, together with rules for rewriting them, make a combinatory algebra, and and are its basic combinators.
1.2 Confluence
The rules () and () let a step happen anywhere inside a term, so a term can often step in more than one way. Take
which is applied to . A run can start at the front or in the argument, and here are both:
Both runs end at , and there they stop: nothing in that term can be rewritten.
The term has two first steps because it contains two parts that can each be rewritten on their own. Such a part is a redex, short for reducible expression: a term with the shape of the left-hand side of () or of (), that is, with two arguments or with three. What the rule puts in its place is the reduct. The redexes of are and , and their reducts are and . The term itself is not a redex: it is applied to something more.
Whether a part of a term is a redex depends on the hidden brackets, so it pays to have a routine for finding them.
Read the term from the left. Its first symbol is its head, and the terms that follow it, each a single symbol or a bracketed group, are the head’s arguments.
If the head is with at least two arguments, or with at least three, then the head and its first two or three arguments make a redex.
Then do the same inside every bracketed group.
Here is the routine run on a few terms.
| Term | Its redexes |
|---|---|
| the whole term; the step gives | |
| none: has only one argument | |
| , at the front; the step gives | |
| none: the head is , and is just one of its arguments | |
| , inside the brackets; the step gives | |
| none: has two arguments, and each has one | |
| three: the whole term, , and |
The fourth and fifth rows differ by one pair of brackets. The third shows that a head may have more arguments than it needs: the redex is then the head with its first few, and the rest, here , are carried along unchanged.
The two runs of passed through different terms and arrived at the same one. Is that luck? It had better not be. If a term could run to two different results, “the result of running ” would mean nothing until one also said in what order, and the answer to a computation would depend on the implementation. It doesn’t, and the reason is a theorem.
Theorem 1.6 (Church–Rosser; on loan). If and , then there is a term such that and .
It’s usually remembered as a picture. The two runs at the top are given; the theorem promises the two dashed runs at the bottom.
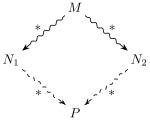
This property is called confluence. In words: however far two runs of the same term have gone apart, each can be continued so that they come back together.5
Some terms can step in more than one way; others can’t step at all. A term with no redex is in normal form. The machines waiting for inputs, such as and , are in normal form, and so are , and the variables on their own. A run that reaches a normal form is over, and the normal form is its result: what the run hands back. What’s normal about it? Nothing deep: it is the standard form a term settles into, if it settles at all.
The routine for finding redexes also says which terms have none. A head that cannot fire, applied to arguments that have no redexes of their own, gives a normal form, and nothing else does.
Lemma 1.7 (the shape of a normal form). A term is in normal form exactly when it has one of the following shapes, where and are terms in normal form:
, for a variable ;
, or ;
, or , or .
In particular, a combinator is in normal form exactly when it is one of , , , and , where and are combinators in normal form.
In words: a variable never fires, however many arguments it has; fires on two and on three; so a normal form is a head with too few arguments to fire, or a variable, applied to normal forms.
Proof. Every term is its head , a constant or a variable, applied to its arguments: . Its parts are the terms for , which run from the head along the arguments, and the parts of the arguments . So its redexes are of two kinds.
At the head. A part is a redex exactly when is and , or is and . There is such a part exactly when is and , or is and .
Inside an argument. These are the redexes of .
The term has no redex, then, exactly when is a variable, or with at most one argument, or with at most two, and each is in normal form. Those are the three shapes. A combinator has no variables, so the first shape cannot occur in it, and the shapes that remain are the five listed. □
So and are normal forms, and is not.
Confluence has two consequences for results, and both are short enough to prove on the spot.
Corollary 1.8 (one result at most). If and , and and are both in normal form, then and are the same term.
Proof. Theorem 1.6 gives a with and . But no step can be taken in a normal form, so the only run from is the run of no steps, and is . In the same way is , and so and are the same term. □
This is what lets us speak of the result of a term: whichever redex a run takes first, it can arrive at only one place.
Corollary 1.9 (no step is a wrong turn). If , where is in normal form, and , then .
Proof. Theorem 1.6 gives a with and , and since is in normal form, is . □
In words: however you have run so far, and in whatever order, its result is still within reach. A poor choice can put the result further off; no choice can put it out of reach, although a run that keeps on choosing poorly need never arrive.
The two runs of took two steps each before they met, but the two sides of a diamond need not be the same length. An step copies its third argument, and with it every redex inside; a step throws its second argument away, and every redex inside with it. So a single step on one side of a diamond may need two steps on the other side, or none. That is why Theorem 1.6 is not obvious: the small diamonds can’t be fitted together like tiles, and the proof has to keep track of a redex and all its copies at once.
Example 1.10 (two lopsided diamonds). Take the term . It has two redexes: the whole term, which is with three arguments, and , inside the third of them. The two runs below take each first.
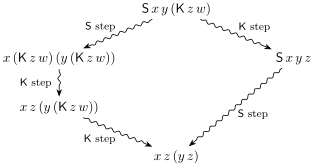
Take the step first, on the left, and the third argument is handed to both of the others: there are now two copies of the redex , and it takes two steps to finish. Take the step first, on the right, and a single step finishes. So the two sides take different numbers of steps, and they meet all the same, at .
The rule for does the opposite. In the outer step throws the inner redex away and gives at once, while the inner step gives , and one more step is needed to reach the same .
1.3 Evaluation Strategies
An implementation of the combinator calculus has to decide which redex to rewrite when a term has more than one. By Corollary 1.8 the choice can’t change the result, but it can change how much work the result takes. The order an implementation follows is its evaluation strategy. Two strategies matter, and between them they divide the languages you use.
Strict, or eager. Rewrite an innermost redex first, one with no redex inside it, and work outwards. In programming terms: run the arguments before the call.6
Lazy. Rewrite an outermost redex first, one that sits inside no other, and work inwards. In programming terms: run an argument only when the function needs it.7
The two strategies part company on the terms of the diamonds above. In a strict run takes the inner step first, down the right of the diamond, and finishes in two steps; a lazy run takes the step first, copies the unrun argument, and needs three. In it is the other way round: the strict run spends a step on an argument that then throws away, two steps in all, and the lazy run needs one.
Why do different languages make different choices? Because each strategy wins in one case and loses in the other. Strict does well when an argument is used more than once, since it runs the argument once and copies the result, and badly when an argument is thrown away, since the work on it was for nothing. Lazy is the reverse.8
Nor does either strategy give you anything the other can’t. A strict language can be made lazy by hand: instead of passing an expression, pass a function that computes it, and call that function only when the value is wanted. A lazy language can be made strict by hand too, by forcing a value before it is passed on. So what divides the strategies is the default, and what the default costs you each time you want the other.
The default is a bet on which behaviour you will want more often. Three considerations bear on the bet.
Predictable cost favours strict. In a strict language the work for an argument is paid at the call, and you can read the cost off the line. In a lazy language the cost of an expression depends on who demands its value and when, and unrun work can pile up unseen: adding up a long list with a lazy accumulator can build a chain of a million unrun additions before it performs one, and the usual remedy is to force the accumulator by hand.
Effects favour strict. Theorem 1.6 licenses any order of steps only where nothing happens on the side. Printing, writing a file, reading input and raising an error are all things that happen on the side. In a strict language they happen in the order written: arguments left to right, then the call. In a lazy language the moment of an effect depends on when its result is demanded, which depends on the rest of the program.9
Modularity favours lazy. A lazy language lets one part of a program describe an enormous or infinite list while another part consumes as much of it as it needs. Strict languages borrow the idea for exactly that reason.10
Everything in this section has assumed that the runs end. Confluence says that two runs of a term can always be brought back together; it doesn’t say that either of them ever stops. Hold that thought until §1.5.
1.4 Programming
The promise so far has been that this tiny calculus captures what a computer can do, and it is time to make good on it. Running a term is plainly a form of computation: a term goes in and a normal form comes out. So we may ask what a language as small as this one can compute. The answer comes in two parts, and both are surprising. First, though, we need a way to write programs in it that a person can read.
A term such as is hard on the eye, and the same patterns turn up again and again. So we’ll give a pattern of terms a name and write the name in place of the pattern. That’s all a definition will be: an abbreviation for a term, with blanks in it to be filled.
Definition 1.11 (definitions). A definition is an equation
where:
is a new name;
are distinct variables;
is a term built from constants, names defined earlier, and the variables alone.
Once defined, the name may be used as a term, and it steps by the rule
alongside the rules of Definition 1.2.
The symbol is read “is defined to be”. It gives something a name, which is a different job from the of arithmetic.11 The rule () says that wherever stands with its arguments, it may be replaced by the right-hand side, with the arguments written in for the parameters; with () and (), that can happen anywhere in a term. That is all a function call is. The above is now official: it is the definition , with no parameters. Three more will be useful:
The first applies a function twice, the second chains two functions into one, and the third swaps the order of two arguments.
Example 1.12 (definitions). Read the definition of against the clauses of Definition 1.11:
is a new name;
and are distinct variables;
the body is built from those two variables by application alone, which the clause for application in Definition 1.1 allows.
A definition can’t reach outside itself. The right-hand side may use the two constants, the parameters and names defined earlier, and nothing else: no numbers, no strings, no if, nothing from a library. A name can’t occur in its own definition either, so there’s no recursion. That looks crippling. It turns out not to be, and the rest of this section is the evidence.
To watch definitions at work we want something visible to come out, and the language has no numbers. So for a page or two we allow ourselves the integers and the operator as ready-made constants, with the obvious step the sum, and we let definitions use them. They aren’t terms of Definition 1.1, so this is a debt, and the numerals pay it: the numbers need not be ready-made, since a language with no numbers can make its own, by making each number a function. A number is “do it times”: a function that takes an and an and applies to that many times.
Definition 1.13 (numerals). For each natural number , the numeral is the name given by the definition
So , and .
Arithmetic is definitions too. To add one to a number, apply once more; to add two numbers, apply the first number of times to the result of applying it the second number of times:
A numeral is a function, and a function can’t be read off the page until it is given something to work on. So give it the ready-made and the ready-made add-one, . Then adds one to , times over, and out comes the digit : the pair , is a printer for numerals.
Example 1.14 (addition, printed). Here is printed, one step per line, with the definition unfolded at each named on the right:
Nine steps, and the answer is : applied to and , the program computes exactly what computes. At the fourth line any of the three occurrences of could have been unfolded, and by Corollary 1.8 the choice can’t change the answer. Exercise 1.1 does the same for multiplication.
A boolean is a choice between two things, so let be the function that keeps the first of two arguments and the one that keeps the second:
With that choice, if b then M else N is simply : the boolean applied to the two branches, with and . There is no if in the language, and none is needed: the boolean is the conditional.
Example 1.15 (booleans). Here are the two cases run:
So if false then 10 else 20 is .
So much for writing programs. Now for the two surprises. The first concerns the defined names. It may look as though they are where the work gets done, and the two constants are scaffolding. It is the other way round: definitions are a convenience, and we can do without them.
Theorem 1.16 (two constants suffice). Let be a definition whose right-hand side is built from , and the parameters alone. Then there is a combinator in and alone such that, for all terms , the term runs to with for each .
In words: anything you can write with parameters, you can write without them. A definition that uses names defined earlier is handled by replacing those names by their combinators first. For instance, does the work of , since , and does the work of , since .
Example 1.17 (composition). Here is run on three arguments:
Four steps, and , without a single parameter.
Example 1.18 (a definition without parameters). The definition of has two parameters and uses twice; the combinator has none, and does the same job:
The is there because is used twice; the work of and is to get each copy to where it is wanted.
The idea behind the theorem is that the variables in a definition are bookkeeping, and that two fixed combinations do all the bookkeeping there is.12 We won’t prove it here; the proof comes with the Deduction Theorem, in the chapter on Hilbert proofs, and it’s a surprise.
Now we can pay the debt of the ready-made numbers. The numerals need nothing but and : take and , so that is , and so on. (Check that .) Then and are the same combinator.13 And , a definition with parameters, is a combinator by Theorem 1.16. The ready-made and were only ever the printer. The step the sum is a shortcut, like a processor’s ADD instruction; real languages build numbers in because it’s fast, and nothing forces them to. We keep the ready-made pieces with a clear conscience.
The second surprise is that what is left computes everything that can be computed. A combinator computes a function on the natural numbers if, for every , the term runs to applied times to .
Theorem 1.19 (Turing completeness). The functions on the natural numbers that combinators in and compute are exactly the functions that Turing machines compute.
Between them, this theorem and the last say that this small language is no toy: anything any computer can compute, a combinator in and can compute, and anything you can write with parameters you can write without them. This theorem we won’t prove at all.14
Recursion is the one thing the definitions seem to lack. No name may occur in its own definition, but a function may be applied to itself, and that is enough. Define
neither of which mentions itself, and run on any :
Write for . The second line says that : hands a copy of itself, and that copy, when it is run, hands another, as many times as the run asks for.15 A function that is to call itself takes the copy as an extra first parameter, and supplies it.
Example 1.20 (factorial). A larger example is factorial, as you’d write it on a whiteboard:
fact(n):
    if n = 0 then return 1
    else return n * fact(n - 1)
Four things in it aren’t in our language:
a parameter;
a name that calls itself;
a conditional;
arithmetic.
And yet it becomes
with no variable, no parameter, no if and no recursive call: only , , a few ready-made arithmetic constants, and application.16 Getting from the whiteboard to this is mechanical: the conditional becomes an application , the recursive call becomes an extra first parameter , and Theorem 1.16 compiles the parameters away. So computes “if then , else times applied to ”.
What is still missing is the loop: something to put in for that behaves as itself does. That is . The copy that hands to is what receives as its , so every recursive call unfolds into once more, and runs to . Recursion was in the language all along, hiding in self-application; §1.5 shows what else hides there.
We’ve taken a great deal away from your idea of a program and added nothing. What’s left is this:
A program is a finite list of definitions together with a term to evaluate.
A definition is an equation.
To run the term is to replace, over and over, a left-hand side by its right-hand side, until no replacement is left to make.
There’s no store, no stack, no instruction pointer, and no order of evaluation to settle: which step you take first can’t change the answer you get (Corollary 1.8), though it can change whether you get one at all.
This language is the general case, reached by deleting from your own languages everything a checker doesn’t read. If you understand the checker for this one, you understand type-checking for all of them. Hold on to that, because something is about to go badly wrong here, and what goes wrong is a thing that goes wrong in yours too. Theorem 1.19 promises as much: this language can do everything a computer can do, and one of the things a computer can do is fail to stop.
1.5 The Monster
Confluence promises that a term has at most one normal form. It doesn’t promise that there is one, and here the connection with computing is the whole point: not every program stops. Nothing in Definition 1.1 says what may be applied to what, and so a function may be applied to itself. Consider the definition
It is the function that applies its argument to itself. That’s an odd thing to want, perhaps, but Definition 1.11 allows it: the right-hand side uses nothing but the one parameter.
Now apply to itself,
and run it:
The step, () for with written in for , returns the term it started from; so there is a second step, and it returns it again, and no number of steps ever finishes. This is the Monster: a perfectly legal construction that nobody who wrote the definitions had in mind. It is the loop of with nothing inside it: does what does, and runs for ever.
So some programs never stop. Why does that matter? Run and there is no output, no error and no crash. The machine is working. It will still be working tomorrow. You’ve met this: a page that spins; a build that never finishes; a request whose reply never comes, holding its connection open, and then a thousand more behind it, until a server that was answering everybody is answering nobody. A wrong answer can at least be read, and argued with. Here the program returns nothing and takes the machine with it.
Changing the notation doesn’t remove the loop. Compiled into the constants, is :
so is , which takes several steps to come back to itself instead of one. Compiling gains nothing: the loop is in the shape of the term.
Nor is there only one monster. There are infinitely many, and here is another, built from a function that uses its argument three times:
Running it gives
The term grows at every step and never repeats. So a loop need not repeat itself, and a checker that watches for a repeat can’t catch them all.
Whether a run stops can even depend on the order of its steps. In §1.3 the order changed only the cost of a run; here it changes whether the run ends. The term has two redexes. The outer one, the step, gives at once, a normal form, and the run stops. The inner one, inside , gives back, and a run that takes it for ever never stops. In the picture the inner steps go right and the steps go down:
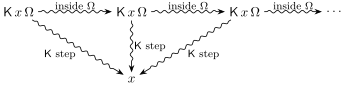
The two strategies of §1.3 fall on opposite sides of this term. A strict run takes the inner step first, so it never reaches the step at all; a lazy run takes the outer step and finishes at once.17
So there is a fourth consideration to add to the three of §1.3, and it favours lazy: termination. For terms built from and , always taking the leftmost of the outermost redexes reaches the normal form whenever there is one.18 A strict run can loop on a term that has a normal form, as it does on ; a lazy run that takes the leftmost outermost redex cannot. If what you most want is an answer whenever one exists, lazy is the safe choice, and the price is paid in the cost and the effects of §1.3. But choosing the order, though it can rescue , is no help to itself: has one redex, so every strategy takes the same step, and none of them gets anywhere.
Be clear about what confluence has and has not promised, because looks at first like a counterexample to it. It isn’t. Corollary 1.8 says that the term has at most one normal form, and Corollary 1.9 says that no step puts it out of reach: after any number of inner steps the step is still there to be taken, which is what the arrows down from the row show. Both are true of . What neither says is that every order of steps reaches the normal form, nor that there is a normal form to reach. Those are different claims, and they are false: the inner-first run of never arrives, and has nowhere to arrive at.
The monsters can’t be banished without giving something up. Theorem 1.19 says that our language computes everything a Turing machine computes, and a Turing machine can run for ever; a language in which every program stops computes less. Nor can we keep the whole language and refuse exactly the monsters. No checker refuses exactly the programs that fail to stop, every one that loops and none that halts: that is the undecidability of the halting problem, and Chapter 8 proves it for these very terms. So we’ll ask for something weaker and get something more useful: a checker that refuses a class of programs we can describe exactly, and that has inside that class.
1.6 Types
What went wrong isn’t hard to name. The function takes an argument and returns a result, and nothing anywhere recorded what kind of argument it takes or what kind of result it gives back. So nothing was in a position to notice that when was handed , it had been handed something it was never built to take. The language has functions and arguments, and no bookkeeping whatever.
The idea is simple, and the rest of this chapter is its execution. Write the bookkeeping down.
Label every term with what it takes and what it returns.
Allow an application only when the argument’s label is the one the function asks for.
Check, before anything runs, that the labels fit together throughout.
The labels are called types.
Definition 1.21 (types). Fix a stock of basic types, such as , and ; I write for basic types when it does not matter which. The types are defined inductively:
Every basic type is a type.
If and are types, then is a type: the function type, the type of functions that take an and return a .
Nothing else is a type.
In one line,
A program of type is a function that takes an input of type and produces an output of type . Read as a contract: “give me an and I’ll return a ”.19 So
is the type of a test on integers;
is the type of something that takes a function;
is a type too, whatever the basic types and .
As with terms, writing out every bracket of a type is cumbersome, and a convention lets us drop most of them. For terms we grouped to the left; for types we make the opposite choice and group to the right: is , a function that takes an and returns a function from to . The type is different: it is the type of a function that takes a function. The conventions are opposite so that terms and types fit together. A function of two arguments takes them one at a time: if and , then , and if also , then . Each convention leaves out the brackets of the commonest shape, and the two shapes match: is , and its type, , gives up its arguments from the left in the same order.
We have the types; now we need to say how to work out the type of a term, written and read “ has type ”. But a term such as has variables in it, and its type depends on theirs, so the claim has to carry a list declaring them, written .
Definition 1.22 (context). A context is a finite list pairing each variable in scope with a type, no variable listed twice. The empty list counts, and I write for with the pair added at the end.
A context is what a programmer would call the declarations in scope. It may also declare ready-made constants, as the text after Definition 1.24 explains. The checker’s basic claim is made in a context.
Definition 1.23 (judgement). A judgement is a claim
read “ has type when its variables have the types gives them”. When is empty it is written .
When is empty, is a program with type outright. The subscript names the system, the typed combinators, KS after the two constants and ; every system in these notes carries a subscript of its own, so that a turnstile always says which system it belongs to.
The question for us is this: given a context and a term , which type, if any, may have? Suppose declares . Then should be well typed only when is an integer, and is then an integer itself. All a checker does is confirm, before anything runs, that your code keeps to this discipline throughout. By Definition 1.1 there are four kinds of piece to check, one for each way of building a term (counting the two constants separately). The constants have fixed types, a variable has the type the context gives it, and an application is typed from the types of its two parts; it is there that a checker says no.
The certificate the checker produces is called a typing, and it is laid out as a proof is laid out on paper: what is given at the top, a line under it, and below the line an argument in which every step is numbered and carries its reason.
Definition 1.24 (typing). The two constants have the type schemas
where , and stand for arbitrary types: each line is a schema, and gives one type for each choice of letters.
Let be a context, a term and a type. A typing of is a finite sequence of judgements
whose last judgement is , and in which each judgement , read “ has type in the context ”, is justified in one of four ways:
(K) is , and is an instance of (1.1);
(S) is , and is an instance of (1.2);
(var) is a variable (or a ready-made constant, see below), and is declared in ;
(app) there are two earlier judgements and , with , such that is the type and is the term .
If such a typing exists, we write , and say that the typing witnesses .
We set a typing out as a box, with the context above the horizontal line and the judgements below it, one to a numbered line, each with its justification on the right:
| Line | Formula | Justification |
|---|---|---|
| 1 | reason | |
| 2 | reason | |
| n | reason |
Each line is really the judgement , with the left off because it is the same all the way down; the vertical line is there to say so. A declaration in is one that stands above the line. The justifications are written like this:
“(app) , ” names line as the function and line as the argument;
after (K) or (S) I give in square brackets the types put for the schema’s letters.
If the word schema is new, the idea is not. Schema (1.1) is one line, but it gives a type for every choice of and : , and , and , each of them a typing of .20
The integers, the operator and the strings aren’t terms of Definition 1.1, so a typing has no case for them, and needs none. A program that uses them has to say what they are, and it says so in the context. The declarations , and (so that is applied to and then to ) are declarations like any other, and a line that uses one is justified by (var). Only the pieces a term actually uses need be declared. A term that uses none, such as , is typed in the empty context.
Example 1.25 (a first typing). Recall that if b then M else N is just and that , so that if true then 3 else 4 is . Let us type it. It has no variables, but it uses two ready-made numerals, and a checker has to be told what they are, so they are declared above the line.
| Line | Formula | Justification |
|---|---|---|
| 1 | (K) | |
| 2 | (var) | |
| 3 | (app) 1, 2 | |
| 4 | (var) | |
| 5 | (app) 3, 4 |
The last line is , so the box witnesses : an , and we know it before anything runs. Declare in place of and choose to be in line 1, and too: doesn’t care what it drops.
Example 1.26 (a typing with parameters). Now a term with parameters: the body of . To type it, declare its parameters, .
| Line | Formula | Justification |
|---|---|---|
| 1 | (var) | |
| 2 | (var) | |
| 3 | (app) 1, 2 | |
| 4 | (app) 1, 3 |
Line 1 is cited twice, which is allowed. The context is the parameter list.21 The last line is , so the box witnesses .
The definition has no case for a name. It types constants, variables and applications, and a name introduced by a definition is none of the three: to type itself, or , the checker would need the type of the name, and nothing above gives it one. A rule for names is still missing.
A typing is easy to check, and finding one can take search. A checker that has to find types instead of being told them22
gives each unknown type a letter;
reads off from the rules the equations the letters must satisfy;
solves them.
The procedure is called unification, and it works backwards from the goal, not forwards from the constants.
Example 1.27 (the identity, typed). The typing of at the type is below. The square brackets name the types substituted for the schema’s letters, in order.
| Line | Formula | Justification |
|---|---|---|
| empty context | ||
| 1 | (S) | |
| 2 | (K) | |
| 3 | (app) 1, 2 | |
| 4 | (K) | |
| 5 | (app) 3, 4 |
Five lines, and the last is , so the box witnesses . Nothing stands above the line: there are no variables and nothing ready-made, so the context is empty.
To find line 1, leave the letters of (S) unknown, and let the two s decide them.
The goal is .
(S) gives , so ; hence and .
The first must have type , which has the shape of (K) whatever is.
The second must have type , and the shape forces for some .
Any will do. Choose : then , and that is line 1.
The search took a paragraph; the check takes none. Line 1 is the line nobody would write unprompted, and unification finds it.
Two schemas, one look-up, one match: that is the whole checker. Read the four cases as the checker reads your code; each schema is just what its combinator does, written as a contract.
(K). keeps: it takes an , then a , and returns the , and (1.1) says so for every choice of and .
(S). shares: it takes a function of two arguments, a function of one, and an argument , and returns . For that to make sense must be what both and expect: , and , and the result is then a . Schema (1.2) is that sentence written down.
(var). A variable has the type it was declared with, and the checker has only to look up in .
(app). An application is well typed only if is a function and is an argument of exactly the type expects, and then the result has ’s result type. When the types don’t match, this is the case that draws the red line.
Example 1.28 (the red line). Back to the line from the start of the chapter: total = 3 + "hello", underlined in red, with the message expected Int, got String. Without types nothing stops it: inside the machine and are both just bits, and the processor would add them. Now add the checker, and try to type .
| Line | Formula | Justification |
|---|---|---|
| 1 | (var) | |
| 2 | (var) | |
| 3 | (app) 1, 2 | |
| 4 | (var) | |
| 5 | (app) 3, 4 refused |
Line 5 should be (app) applied to lines 3 and 4. But (app) needs the argument’s type to be the of the function’s , and here the function wants and is offered . Nor is there another way round: since is declared at alone, line 3 gives the only type the function can have.
No rule applies, there is no typing, and the checker refuses, before anything runs. That refusal, expected Int, got String, is the whole content of the error your editor shows, minus the decoration a real language adds.
1.7 Subject Reduction
The checker gives its verdict before the program runs. But running rewrites the term: , and the checker typed , not . Is the term we end up with still an ? If a single step could turn an into a , the checker’s yes would expire half-way through the run, and every guarantee with it. You rely on this not happening: a variable declared int never ends up holding a String while the program runs. In our language the reason is a theorem, and one we can prove.
Theorem 1.29 (subject reduction). If and by a step, an step or a ready-made step, then .
Proof. First the cases in which the whole of is the part rewritten, and then the case in which that part sits inside something larger.
A step. Then is and is . Read the typing of backwards twice. The line came by (app) from and , and the line came by (app) from and . Schema (1.1) gives no types but those of the shape , so . Hence , which is what we want.
An step. Then is and is . Reading backwards three times gives , , and , and schema (1.2) forces , , and . Now build the typing of forwards:
(app) on and gives ;
(app) on and gives ;
(app) on those two gives , and is .
A ready-made step. the sum: declares and the integers, as the context of any term that uses them does, so both sides have type .
Inside a larger term. If the part rewritten is a proper subterm of , the lines of the typing that type that subterm are replaced by the lines just constructed, which end in the same type; every later line of the typing is unchanged, because (app) looks only at the types of its two parts and not at what they are.
□
In words: the verdict the checker gave before the program ran stands as the program runs. At every step the term in hand still has the type the checker assigned, so an argument of the wrong kind can never arise part-way through, however long the run. What the checker said stays said. Without this theorem, a type system would be pointless.
Subject reduction says that no step goes wrong. It doesn’t say that the steps come to an end, and the Monster was a program whose steps never do. The next theorem says that no typed program behaves like that.
Theorem 1.30 (normalisation; on loan). If , then has a normal form.
This bans the Monster and all its kin. The term has no normal form, so by the theorem it has no typing; and since (app) types an application only when both of its parts are typed, no term with inside it has a typing either. A typed program, then, is safe in both senses: by subject reduction no step goes wrong, and by normalisation the run ends. That answers the question the chapter began with. A checker that looks only at kinds can keep out every program that never stops. The price is that it keeps out some that do stop, and , which has a normal form and no typing, is one of them. We take the theorem on trust.
The theorem comes in two strengths. The weaker says that some order of steps always finishes: always take the step whose function has the most complicated type, and a measure of the term goes down at every step, and cannot go down for ever. That is enough for Theorem 1.30 as stated. The stronger says that every order of steps finishes. No simple measure works for every order; the proof instead shows something stronger than “finishes”, by induction on the type, and that is a technique this course doesn’t reach.23
Given the stronger form, the choice between strict and lazy that mattered for makes no difference to a typed program: it finishes either way. So the termination consideration of §1.5 disappears for typed programs, and what is left to choose between is the cost and the effects of §1.3. Every real language gives the loop back by adding recursion under another name (a loop, or a function that calls itself), and Exercise 1.6 asks what that costs.
History
The combinators were discovered twice in the 1920s, when there were no programs to write: by Moses Schönfinkel, working in Hilbert’s Göttingen, and by Haskell Curry, a young American teaching mathematics at Harvard. Both were after something in logic, and to see what, we need the logic of the day.
In the 1920s mathematicians wanted a rulebook for the whole of mathematics: a system in which a proof could be written down and then checked step by step, by rule alone, with no judgement needed. Checking by rule alone, without running anything, is exactly what your type checker does to a program; they wanted it for every proof in mathematics. The great attempt was Whitehead and Russell’s Principia Mathematica (1910–13), and it worked, at a price: it takes hundreds of pages to reach .24
Schönfinkel was after economy. He wanted to build logic from as few basic notions as possible, and the title of his paper, On the building blocks of mathematical logic, says as much. Its surprise was that the variables of logic, the in “for every ”, could be done away with altogether, and that the two operations we have called and could do the variables’ work. He introduced them in a talk at Göttingen in 1920, and a colleague, Heinrich Behmann, wrote the talk up for publication in 1924. Schönfinkel returned to Moscow, fell ill, and died in poverty in 1942; it is said that his neighbours burned his papers for heat. The two letters and are most of what survives of him.
Curry, reading the first chapter of Principia, was bothered by something small. One of its rules, detachment, is as simple as a rule can be: from and “if then ”, conclude . Another, substitution (putting one formula in place of a variable throughout another), was far more complicated. A rule that basic, Curry thought, ought to be simple too.
So he set out to take substitution apart, and found that it came apart into very little. Whatever a variable is doing in a formula, it is being kept, thrown away, copied or moved; so a few fixed operations that keep, throw away, copy and move their arguments can do all the work that variables do. Those operations are the combinators: throws an argument away and copies one, and that is why the two of them turned out to be enough.25
Curry’s plan was bigger than substitution. If combinators could do the work of variables, they could sit underneath the whole of logic: one would build the logic itself from constants and application, and the rulebook for mathematics would rest on a handful of constants and the rules for running them. You’ve seen in this chapter why that might work. Functions can be everything: the booleans, the numbers and addition were all built from and . And a calculus of functions has only a few simple rules, easy to work with and easy to check.
So what could go wrong? A great deal, as it turned out. Within a few years the logic was shown to be inconsistent (Kleene and Rosser, 1935).26 Curry’s logic is not worth developing here. What broke it is worth seeing, though, because it is the Monster in another guise.
The first break came in 1935, from Stephen Kleene and Barkley Rosser, and it used an old puzzle of Jules Richard’s (1905). The phrases of English that describe functions on numbers (“add one”, “double the number”) can be listed, shortest first, so the functions they describe come in a list too: . Now go down the diagonal and add one, , so that differs from at , from at , and from every function on the list somewhere.
But “add one to what the th function on the list gives at ” is itself an English description. So is on the list, say , and then : a number equal to itself plus one.
In English the blame falls on “the th function on the list”, which isn’t a precise description, since nobody ever pinned down which phrases count as descriptions. A logic made of combinators can pin it down, inside itself: Kleene and Rosser (1935) showed that it can list its own definitions and carry the construction out, and so it proves , and hence .27
Richard’s and the Monster are the same construction. Going down the diagonal means applying the th function to its own number, ; and when meets itself, at , it is applied to its own number too. That is self-application, the move makes, dressed up as a list. Read Richard’s equation as a rule for running instead of as a claim, and it is a monster:
a run that grows at every step and never ends, as the run of did. A logic and a program fail differently on the same construction. The logic believes its equations, so it concludes that a number is equal to itself plus one, and from there anything at all.28 The program only runs them, and so it never stops. Either way the trouble is a thing made to act on itself.
Look at the Monster through its types and the self-reference is plain to see. Suppose could be typed, and give its parameter some type . In the body , the first is a function, so its type must be for some , and the second is its argument, of type . But it is the same , with one type, so
The type of would have to contain itself as a proper part, as Richard’s had to be on the list it was defined from. No type does: is longer than , and a type can’t be longer than itself. So has no type, and the checker refuses the Monster at the very step where it applies something to itself.29 The of §1.4 is refused for the same reason, since it is built from the same .
That is the repair, and it is the one that lasted. Curry had begun giving his combinators types in 1934, and Church built them into his logic in 1940.30 Types sit outside the language of terms: they are built from basic types by arrows, and “” is a judgement the checker makes by four rules, not a term that could be applied to itself. A thing that must take itself as an argument has no type, so it can’t be written, and the diagonal never gets started. Your compiler is built on the repaired discipline, and that is why the checker’s whole job is to refuse. So of the two options we started with, the compiler’s certainty was the theorem.
A logic needed saving, and programmers inherited the repair: Figure 1.1 gives the dates.
| Year | Event |
|---|---|
| 1920 | Schönfinkel introduces and in a Göttingen talk (printed 1924). |
| 1920s | Curry, puzzled by substitution in Principia, rediscovers the combinators; thesis 1929, printed 1930. |
| 1934 | Curry works out the types of and , and recognises them as the first two of Frege’s axioms for implication. |
| 1935 | Kleene and Rosser: Curry’s logic, built from combinators, is inconsistent. |
| 1936 | Church and Turing: what can be computed. Church and Rosser: the order of steps does not change the answer. |
| 1940s | Turing: some order of steps always finishes (unpublished). |
| 1942 | Curry’s paradox: the short version. |
| 1967 | Tait: every order of steps finishes. |
| 1972 | Girard extends Tait’s idea to polymorphism, the theory of generics. |
| 1980 | Gandy publishes Turing’s proof. |
Summary
Let me gather it up. Under every language you use is a combinatory algebra: two constants and application, run by two rewrite rules, in which every definition you’ve ever written can be expressed; and unpoliced it computes everything, including a program that never stops. A run may take its steps in any order: by the theorem of Church and Rosser the order cannot change the result, a normal form, though it can change whether a result is reached.
A type is a contract, a basic type or ; the checker’s job is to allow an application only when the contract is met. Its certificate is a typing: the context above a line, and below it a list of numbered lines , each justified in one of the four ways (K), (S), (var) and (app), and it witnesses the judgement its last line states. Its no is case (app) failing to match, as it does for and for the self-application inside the Monster. Its yes mentions no input and so covers every input: by subject reduction what it says of a program stays said at every step of the program’s run, and by normalisation the run ends.
Exercises
Exercise 1.1. Let . Run by the rules of Definitions 1.2 and 1.11, one step per line, naming each. Then say what computes in general, and why the definition has three parameters where had four.
Exercise 1.2. Example 1.17 wrote with no parameters. Do the same for : run by the rules of Definitions 1.2 and 1.11, using the runs of and as single steps where they help, and confirm that it reaches . Which of the three things a parameter can do (be used once, several times, or not at all) does each of and take care of here?
Exercise 1.3. Using Definition 1.24:
In the context , give a typing of , the term that runs to after two steps.
Give a typing of the program itself, with the empty context.
Keep both typings; the chapter on Hilbert proofs uses them again.
Exercise 1.4. §1.5 said that Python takes the inner step of and Haskell the outer one. Watch it happen: in Python define K = lambda a: lambda b: a and w = lambda x: x(x) and evaluate K(1)(w(w)); in Haskell evaluate const 1 undefined. Then do the same exercise on paper for : find a run that stops and a run that never does, and say which of them each language takes. Does either contradict Theorem 1.6?
Exercise 1.5.
Give typings of and of .
Then run for an arbitrary , and say what is.
Finally, find one type that and both have, and say why it is the right type for a boolean.
Exercise 1.6. Every real language has recursion, but the of §1.4 has no type, since it is built from (§1.7). So a typed language that wants recursion has to add it. Model it by a new constant with the step and the rule , for every type .
Exercise 1.7. This exercise goes with §1.2.
Find every redex in each of these terms, and say which of the terms are in normal form:
The last of these has two redexes. Run it to normal form twice, once taking each redex first, and draw the diamond that Theorem 1.6 promises.
In the diamond for (§1.2), the run that took the outer step first was the longer. Find a term in which it is the shorter. Which order does a strict language take, and which a lazy one (§1.3)? Is either order always the quicker?
Exercise 1.8. This exercise goes with the bracket convention of §1.1 and with Example 1.5.
Put in all the brackets in
Then take out every bracket that the convention makes unnecessary from
Find every redex in and in , and run each to its normal form. Which of the two reaches ? Which has two redexes, and do both orders agree?
Python’s
def k2(a, b): return atakes a pair. Writecurryanduncurry, one line each, such thatcurry(k2)(1)(2)gives1and so doesuncurry(K)(1, 2), whereK = lambda a: lambda b: a. What happens onk2(1), and what onK(1)? Which of the two is a term of our language?
Exercise 1.9. This exercise goes with §1.3. Let be the term , which runs to in two steps.
Run three ways:
strictly;
lazily, running each copy of separately;
lazily with sharing.
Count the steps in each.
Do the same for , strict and lazy only.
In Python,
my_ifwritten to take its branches as plain expressions,def my_if(b, m, n): return m if b else n, together withdef fact(n): return my_if(n == 0, 1, n * fact(n - 1)), makesfact(5)raise aRecursionError. Without looking back at the text:rewrite
my_ifso that its second and third arguments are functions to be called when wanted;change
factto match;check that
fact(5)is120.
In one sentence, say what the
lambda:s are doing.When an argument is used twice, and when it is thrown away, which strategy does the less work, and what does sharing add?
References
- Alonzo Church. An unsolvable problem of elementary number theory. American Journal of Mathematics, 58(2):345–363, 1936.
- Alonzo Church. A formulation of the simple theory of types. Journal of Symbolic Logic, 5(2):56–68, 1940.
- Alonzo Church and J. Barkley Rosser. Some properties of conversion. Transactions of the American Mathematical Society, 39(3):472–482, 1936.
- Haskell B. Curry. Grundlagen der kombinatorischen Logik. American Journal of Mathematics, 52:509–536, 789–834, 1930.
- Haskell B. Curry. The inconsistency of certain formal logics. Journal of Symbolic Logic, 7(3):115–117, 1942.
- Haskell B. Curry and Robert Feys. Combinatory Logic, Volume I. North-Holland, Amsterdam, 1958.
- Stephen C. Kleene and J. Barkley Rosser. The inconsistency of certain formal logics. Annals of Mathematics, 36(3):630–636, 1935.
- Mars Climate Orbiter Mishap Investigation Board. Phase I report. Technical report, NASA, Washington, DC, November 1999.
- Moses Schönfinkel. Über die Bausteine der mathematischen Logik. Mathematische Annalen, 92:305–316, 1924.
- William W. Tait. Intensional interpretations of functionals of finite type I. Journal of Symbolic Logic, 32(2):198–212, 1967.
- Alan M. Turing. Computability and -definability. Journal of Symbolic Logic, 2(4):153–163, 1937.
Notes
The longer story: for two thousand years, from Aristotle on, logic lived in philosophy. For three hundred more, from Descartes and Leibniz, it lived in mathematics as well. Then, from 1879 into the 1920s, Frege, Russell and Hilbert rebuilt it almost from scratch. The logicians of the 1930s who arrived at the machine were Gödel, Church and Turing. ↩
A gentler example of the same bug: in 1983 an Air Canada Boeing 767 ran out of fuel in flight because its fuel load had been worked out in pounds instead of kilograms. The pilot glided it down onto a disused air-force strip at Gimli, Manitoba, then in use for drag racing, and everyone on board survived. ↩
Java and Rust were born with theirs. JavaScript grew one, called TypeScript, when the untyped web became unmanageable, which may be the most polite sentence anyone has written about JavaScript. Python, in 2015, acquired the means for one: type hints. ↩
After Haskell Curry, who also has a programming language named after him, and who used the idea so much that the name stuck. Schönfinkel did it before Curry (and Frege, in passing, before both); “schönfinkeling” never caught on. ↩
Church and Rosser proved it in 1936 (Church and Rosser, 1936), for a close cousin of this calculus, the -calculus, and it holds here too. ↩
Python, Java, C, JavaScript and ML work this way. ↩
Haskell works this way. ↩
A lazy implementation can repair half of its weakness by sharing: it copies a pointer to the unrun argument instead of the argument itself, so that the two copies of above are one object, run once, when it is first needed. This is call by need, and it is what Haskell does; the price is the bookkeeping for each suspended argument, called a thunk. The other two names you’ll meet are call by value (strict) and call by name (lazy, without sharing). ↩
Haskell’s answer is to keep effects out of ordinary expressions and to mark them in the type, which is workable and costs something in every program that prints. ↩
In Haskell
take 3 [1..]is[1,2,3]. Python’s generators and Java’s streams are lazy sequences inside strict languages. ↩In C,
=means assignment,==means equality, and===means JavaScript. Our means “I am naming this”, and claims nothing. ↩The theorem is Moses Schönfinkel’s (Schönfinkel, 1924). ↩
C programmers have suspected this for years. ↩
It is due to Alonzo Church (Church, 1936) and his student Alan Turing (Turing, 1937), for the closely related -calculus, and it carries over to combinators. ↩
Run it lazily. A strict run unfolds inside the argument for ever, and strict languages use a variant of that waits for its argument. The most famous combinator in Silicon Valley is a venture fund: Paul Graham named Y Combinator after this one. A type checker forbids it (§1.7). ↩
Nobody would ever write this. Nobody has to: a compiler would. ↩
Real languages behave the same way. In Haskell, which is lazy,
const 1 undefinedis1. In Python, which is strict, withK = lambda a: lambda b: aandw = lambda x: x(x), the callK(1)(w(w))never returns1, and Python gives up only when its stack runs out. Exercise 1.4 asks you to watch both happen. ↩This normalisation theorem for combinators is Curry and Feys’ (Curry and Feys, 1958). ↩
In Java,
Function<A, B>is the type of functions that take anAand return aB, which is . More:A method
static int square(int n)has type ;the test
n -> n % 2 == 0has typeFunction<Integer, Boolean>, which is ;the addition
m -> n -> m + n, which takes its arguments one at a time, has typeFunction<Integer, Function<Integer, Integer>>, which is , nested to the right just as our arrow is.
A schema is what Java, Rust and TypeScript call a generic: in Java, is
static <A, B> Function<B, A> k(A a) { return b -> a; }, and the types the compiler chooses forAandBat each use of are the types written in square brackets after (K) in a typing. ↩In Java,
static int twice(Function<Integer, Integer> f, int x). ↩Haskell’s, OCaml’s and Rust’s, for instance. ↩
The weaker form is Turing’s, from the early 1940s. He never published the proof; Robin Gandy printed it in 1980, long after Turing’s death, in a volume of essays for Haskell Curry. The stronger form is Tait’s, from 1967 (Tait, 1967), and Girard took his technique in 1972 to polymorphism, the theory behind generics. ↩
Principia finishes the proof of only in its second volume (1912), at proposition 110.643, and adds the remark: “The above proposition is occasionally useful.” ↩
In 1927, at Princeton, Curry came across Schönfinkel’s paper of 1924 and found that he had been beaten to the idea; he was, for a while, distressed. He went to Göttingen all the same, where Hilbert examined his thesis on combinatory logic in 1929 (Curry, 1930), and he spent the next fifty years on the subject. A programming language and a verb (currying) are named after him; nothing is named after Schönfinkel. ↩
Curry wasn’t alone. Alonzo Church, at Princeton, had built a logic on the same plan in 1932, writing his functions with , in what became the -calculus, instead of combinators, and the same paradox broke both. ↩
Kleene and Rosser were Church’s doctoral students, and the same argument broke Church’s logic too. Every supervisor’s nightmare: your students break your system. It worked out; both became giants of the subject. ↩
Curry (1942) later found a shorter version, with no numbers and no list: a statement that says of itself “if I hold, then ”, for any you like. ↩
In unification this failure has a name, the occurs check: a letter may not be set equal to a type in which it occurs. Ask Haskell for the type of
\ x -> x xand it complains of an infinite type, which is in its own words. ↩Church’s repaired logic is the simply typed -calculus (Church, 1940). ↩